gemma-4-e4b · server http://erwing · run 2026-10-12 15:37:37 → 2026-10-12 15:42:46
OVERALL
Composite: 7.1 ✓ 8/8 tests
Speed (median): 36.9 tok/s
Thinking cost: 0 tokens · ≈0s · starved: none
ENVIRONMENT & LOAD (verified)
Gemma-4-E4B-it Q4_K_M on a GTX 1080 8 GB — TUNED llama-server config (direct , no vision tower, Q8_0 KV, all layers GPU): 5,240 / 8,192 MiB at 128K context with 2.9 GiB headroom, 35.5 tok/s. LM Studio's default load (vision tower + f16 KV + KV in system RAM) spills ~1.5 GiB of weights and runs 21–23 tok/s instead. Composite 7.1 (8/8). Every VRAM number measured with nvidia-smi per config.
| Server | llama.cpp 2.55.0 llama-server.exe (run from LM Studio's backend folder with the CUDA vendor DLL dir prepended to PATH; LM Studio left unloaded) |
| Model file | gemma-4-E4B-it-Q4_K_M.gguf — weights 6,030 MiB |
| Vision tower | EXCLUDED (no --mmproj). LM Studio default loads the ~900 MiB BF16 mmproj onto the GPU — that is what breaks the fit |
| KV cache | Q8_0 (cache-type-k/v q8_0), measured ≈9 KiB/token, fully on GPU |
| VRAM ladder (measured) | 32K = 3,944 MiB · 64K = 4,376 MiB · 128K = 5,240 MiB (nvidia-smi, server-only configs) |
| Speed ladder | 32K = 31.1 tok/s · 64K = 35.7 · 128K = 35.5 · benchmark speed test = 36.9 tok/s |
| LM Studio default comparison | 21–23 tok/s at 32K–128K — mmproj + f16 KV + --kv-offload caused weight spill; REST load cannot set KV quant (GUI-only) |
| Context ceiling | 128K is the model's native max AND fits with room to spare — no ceiling reached on this card |
Observations
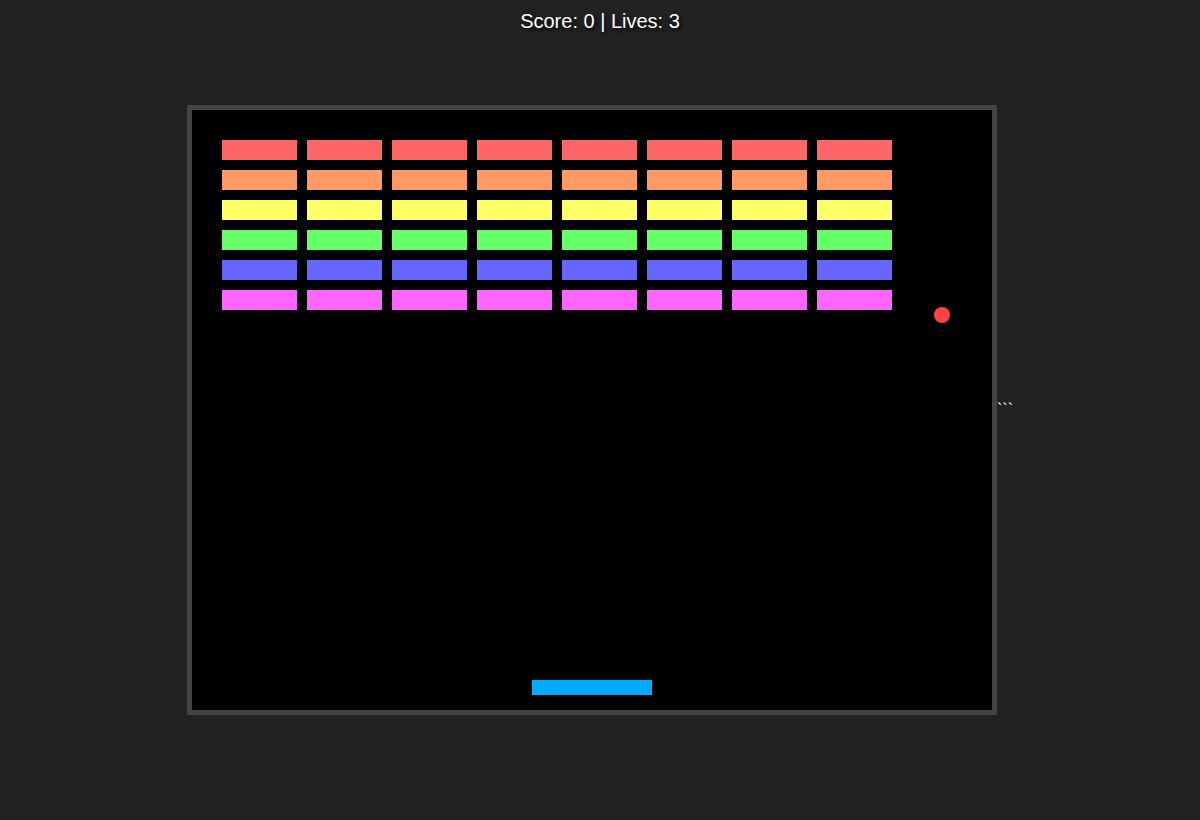
· [assistant] breakout 9/10: fully rendered (bricks, paddle, ball, HUD), 0 JS errors. (verified by screenshot)
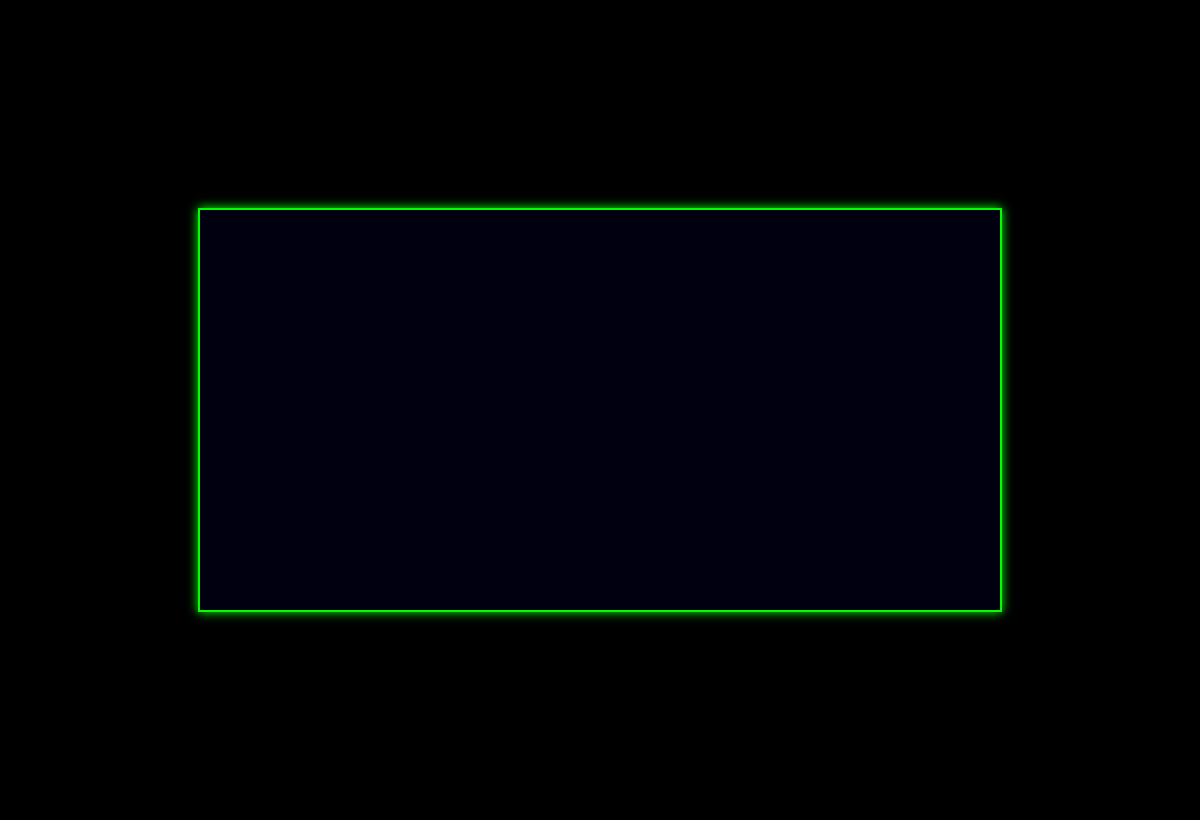
· [assistant] delta 2/10: canvas frame drawn but script died on a JS syntax error ('Unexpected token ,') — nothing renders. (verified by screenshot + page.json error)
· [assistant] fractal 2/10: runtime error 'Math.sin(...).normalize is not a function' at load — hallucinated API, canvas blank. (verified by page.json error)
· [assistant] reasoning 9/10 (correct, concise), creative 8/10 (complete story with twist). No thinking tokens — direct-answer model. (verified from outputs)
· [user] 'you seem to be using a lot of ram spilling from the vram' — confirmed: LM Studio defaults offloaded weights AND KV to the 16 GB system RAM. (confirmed via llama-server cmdline + nvidia-smi)
Still to verify
· LM Studio (the Hermes provider path) still uses spilling defaults — GUI settings (KV Q8_0, vision off, parallel 1) not yet applied on erwing.
· Games delta/fractal are genuine model failures (not harness artifacts) — a re-test would only matter after a model update.
RAW TEXT / CODE OUTPUTS
speed.txt (140 bytes, full file beside this page)1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
fib.txt (126 bytes, full file beside this page)def fib(n):
if n <= 1:
return n
a, b = 0, 1
for _ in range(2, n + 1):
a, b = b, a + b
return b reasoning.txt (101 bytes, full file beside this page)**Reasoning:** The phrase "All but 9 die" means that 9 sheep survived the event.
**Final Number:** 9
constraints.txt (314 bytes, full file beside this page)The sky wept a steady curtain of silver, blurring the edges of the world into a watercolor wash. Raindrops drummed a soothing rhythm against the windowpane, accompanied by the distant rumble of thunder. Inside, the quiet comfort of a warm beverage and a good book offered perfect sanctuary from the gray afternoon.
json.txt (78 bytes, full file beside this page){"name": "Elara Vance", "age": 31, "hobbies": ["hiking", "baking", "reading"]} creative.txt (628 bytes, full file beside this page)Elara monitored the containment unit, its crystalline glow pulsing with slow, rhythmic energy. The station’s hum was a comforting blanket against the vast silence of space. She logged the readings: stable, predictable, beautiful. For six months, she had studied the object, convinced it was an extraterrestrial life form.
She reached out, her gloved finger hovering near the shimmering crystal. It flared, bathing the console in sudden, warm light. Satisfied, Elara straightened up and glanced at her reflection in the viewport glass.
The crystal pulsed again, and her reflection smiled back—a smile that didn't belong to her.